

Comparing search performance before and after a Splunk platform version upgrade
This article looks at whether a Splunk platform version upgrade affects search performance, using search runtime as the benchmark. Previous comparisons looked at search head hardware changes and their impact on search performance and search head performance gains after upgrading a low-utilization cluster. This article runs a similar comparison based on two weeks of pre-upgrade data (version 9.3.3) and two weeks of post-upgrade data (version 10.2.5).
The findings in this article reflect a specific version upgrade comparison carried out by the author, Gareth Anderson, in his own environment, so your results might vary depending on workload, search complexity, data volume, and environment configuration. You should treat these results as a reference point and benchmark against your own environment before making upgrade decisions.
What was compared
The Splunk platform upgrade procedure requires an intermediate version when upgrading to 10.2.x from 9.3.3. This comparison used an intermediate version of 10.0.8. Because the environment stayed on 10.0.8 for a matter of hours before moving to 10.2.5, that intermediate version is not included in the comparison.
The comparison covers a 5-week period, with only 4 weeks of data included. The week immediately after the upgrade was excluded because of stability and post-upgrade issues.
Because the upgrade was platform-wide, statistics were gathered across 5 search head clusters and a few standalone search heads. Due to the lower search volume on the quieter standalone and clustered instances, the comparison focuses on the 3 most heavily utilized search head clusters, referred to here as SH1, SH2, and SH3.
The search used to gather the comparison data was updated to include both dashboard-related data and saved searches. Ad-hoc searches are not included in this comparison. The updated search is in the Search details and result counts section of this article, along with a link to the original search the updated search builds on.
How the runtime changes were measured
The search in the appendix generates a large number of statistics. With over 400,000 statistics returned, the results need a consistent way to be interpreted. The statistics are broken down by search head cluster and phase0/phase1, and include standard deviation, variance between searches, and other properties.
Overall search response times were used to determine improvement, split by:
- Saved searches versus dashboards
- Average versus perc95 runtime improvements
- Both of the above, further split by the runtime range of the query and the search type in use
To keep the numbers in context, the appendix includes statistics on how many search results were used to generate each graph. For each graph, the following limits were applied to exclude outliers from skewing the average performance numbers: avg_phase_0_diff<0.3, phase_0_stdev<50, phase_1_stdev<50, shc_diff>-300, shc_diff<300, indexer_diff>-300, and indexer_diff<300. All queries were based on a phase 0 difference of 0.3 or less, so that searches that vary by more than 30% on average were excluded.
Earlier analysis attempts did not exclude the search head cluster (SHC) difference outliers. Without that exclusion, an occasional search run could go from 7 seconds to 73 seconds for no obvious reason, skewing the overall average.
Summary of findings
The following sections provide a detailed breakdown and graphs of the various performance measurements.
For dashboard search performance, there was significant variance between each search head cluster:
- SH1 saw over 10% improvement in most search runtimes, with the 6–10 second range closer to 30% improvement, backed by a large number of statistics.
- SH2 saw around 16% improvement on average, with around 26% as the highest average improvement in the 30–60 second range.
- SH3 only saw a noticeable benefit in the 30–60 second range (around 14%) and the 600+ second range (around 40%), although the 600+ second range has limited data.
Overall, achieving more than a 10% average decrease in runtime is a significant improvement.
For saved searches, the performance change is different, as expected:
- SH1 saw around 15% improvement at the 6–10 second mark, and mostly around 5% elsewhere, excluding 600+ second searches, which saw a 20% improvement.
- SH2 saw around 10% improvement in most runtimes.
- SH3 saw the least improvement overall, a few percent, excluding 600+ second searches, which saw around 15% improvement (with limited data).
The overall trend is clear: performance improved when moving from 9.3.3 to 10.2.5, more than the difference seen during the previous hardware change (based on SH1). The perc95 graphs show that a subset of searches saw a large reduction in runtime.
Visualizing the performance changes
- ► Click to see SH1 dashboard and saved search performance
-
SH1 dashboard searches
Most dashboards were under the 0.3 threshold used to determine the average difference per search head cluster. SH1 and SH2 are the largest clusters and have the most results to work with. This image shows the SH1 dashboard variance between search runs:

This image shows the SH1 average dashboard performance improvement, broken down by runtime. The average improvement in total runtime is over 10% for most runtime categories, with 30% achieved in the 6–10 second range:

This image shows the SH1 average dashboard performance improvement, broken down by search type. Metrics searches show more benefit than standard searches. The limited data around
pivotandmstatsmight affect the accuracy of this measurement:
This image shows the SH1 perc95 dashboard performance improvement, broken down by runtime:

This image shows the SH1 perc95 dashboard performance improvement, broken down by search type. At perc95, some searches show a significant benefit, greater than the average figures suggest:

SH1 saved searches
Saved searches are often more complex than dashboard searches, and the variance here is a bit larger than expected. This image shows the SH1 saved search variance between search runs:
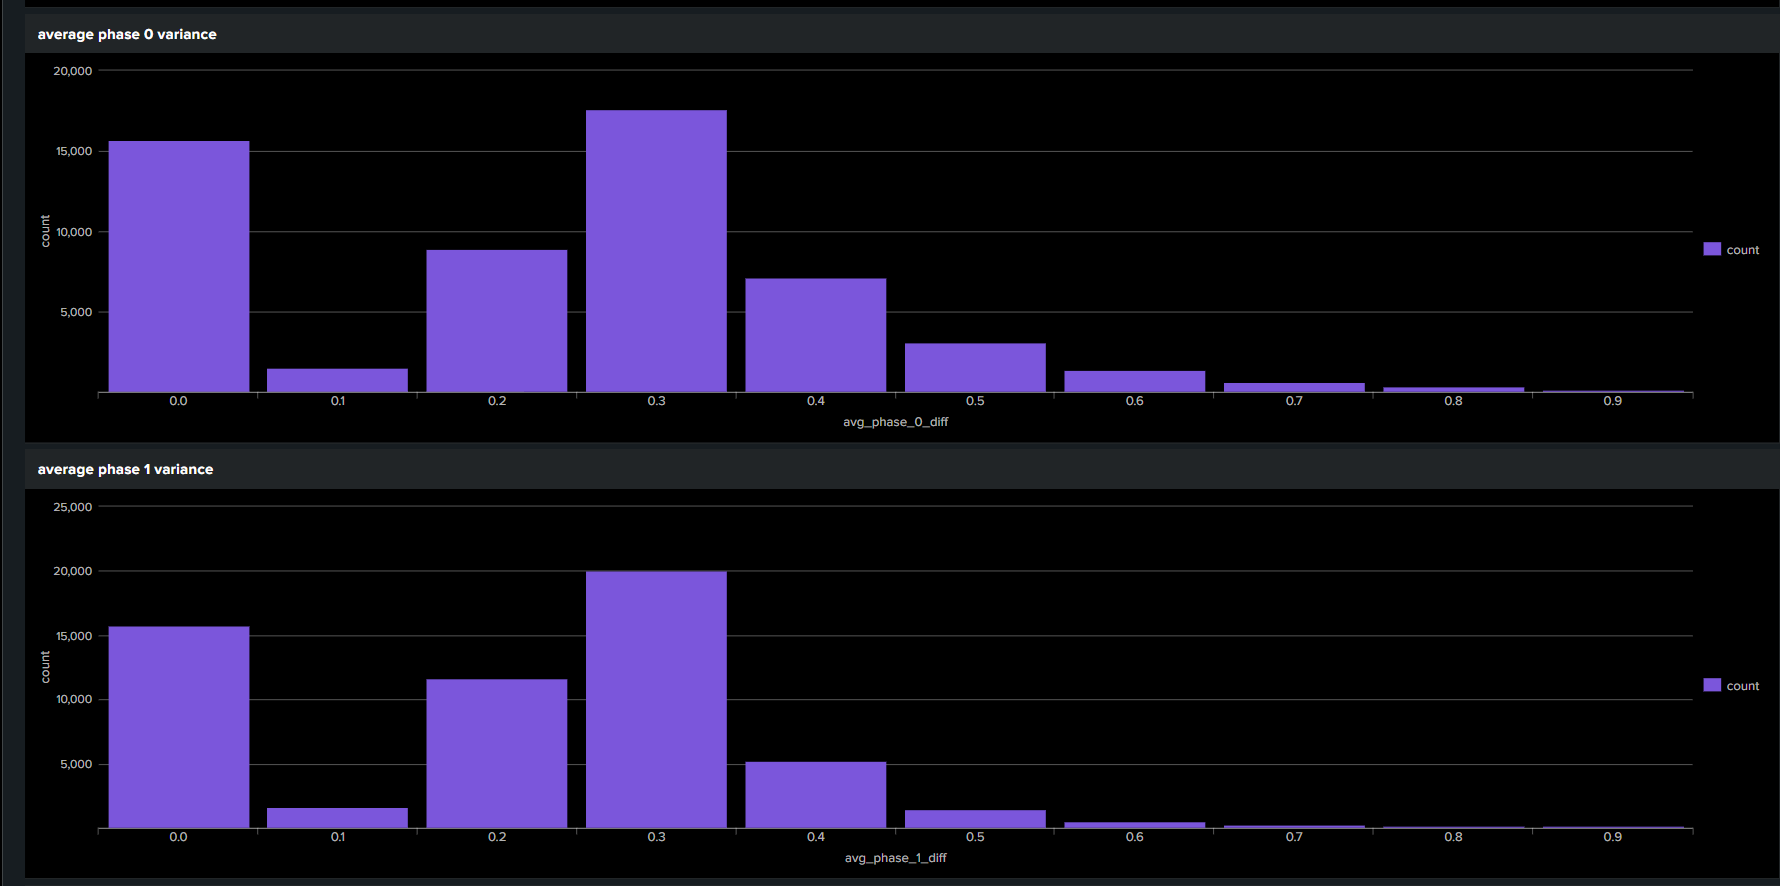
This reduces the number of search results included, but there are still enough results to work with. This image shows the SH1 average saved search performance improvement, broken down by runtime. The performance benefit is significantly less than for dashboards, around 5% or more in most categories, with 20% in the 600+ second category:

This image shows the SH1 average saved search performance improvement, broken down by search type:

This image shows the SH1 perc95 saved search performance improvement, broken down by runtime:

This image shows the SH1 perc95 saved search performance improvement, broken down by search type. The perc95 figures do not show the same increase as with dashboards, but some saved searches do run much faster:

- ► Click to see SH2 dashboard and saved search performance
-
SH2 dashboard searches
SH2 is also a heavily utilized search head cluster. This image shows the SH2 dashboard variance between search runs. The variance on this cluster is quite small compared to SH1:
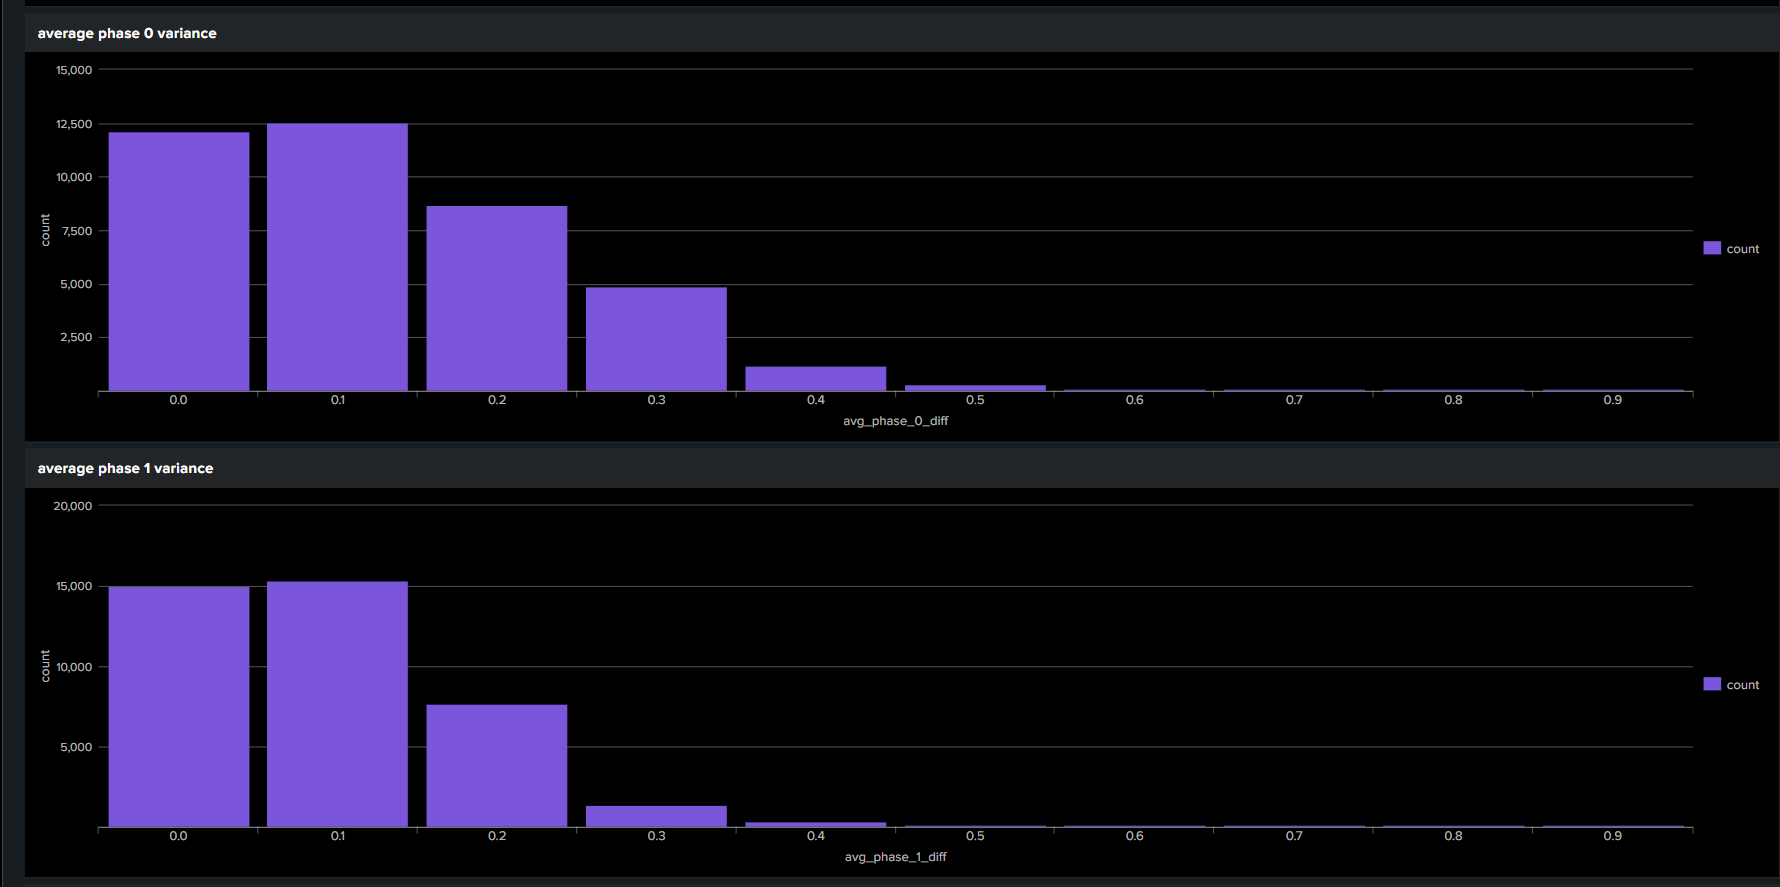
This image shows the SH2 average dashboard performance improvement, broken down by runtime. The benefit is around 15% for most runtime groups or more, with the 30–60 second category achieving over 25% average increases:

This image shows the SH2 average dashboard performance improvement, broken down by search type:

This image shows the SH2 perc95 dashboard performance improvement, broken down by runtime:

This image shows the SH2 perc95 dashboard performance improvement, broken down by search type. The perc95 comparison shows the more extreme edge of the runtime decreases per search.
mstatsshows a larger improvement here, although there are fewer results to compare:
SH2 saved searches
This image shows the SH2 saved search variance between search runs. The variance is a little higher for saved searches, but this cluster is quite consistent:

This image shows the SH2 average saved search performance improvement, broken down by runtime:
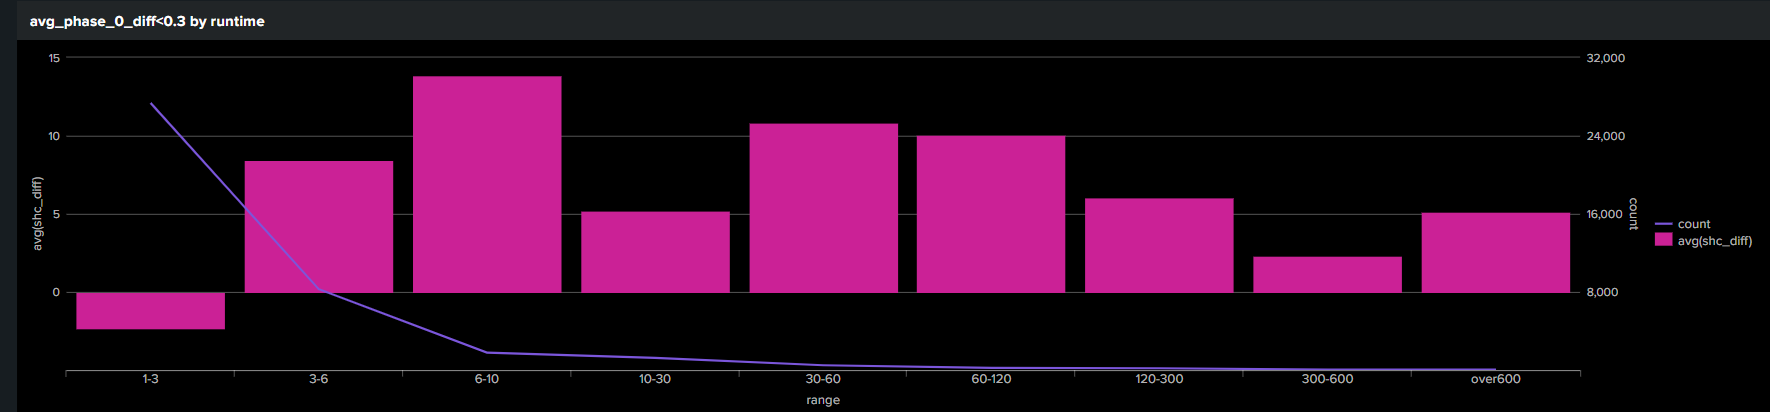
This image shows the SH2 average saved search performance improvement, broken down by search type. The average performance increase varies between 5% and 8% depending on the runtime. The 6–10 second, 30–60 second, and 60–120 second ranges all achieve 10% or more.
mstatsappears to have a significant improvement, although there is limited data available for it:
This image shows the SH2 perc95 saved search performance improvement, broken down by runtime:

This image shows the SH2 perc95 saved search performance improvement, broken down by search type.
mstatssearches show an improvement in this version compared to 9.3.3, although they remain a minority of the searches measured:
- ► Click to see SH3 dashboard and saved search performance
-
SH3 dashboard searches
SH3 has a lower total search count than SH1 or SH2. This image shows the SH3 dashboard variance between search runs. This cluster is quite consistent, although it doesn't have the volume of SH1 or SH2:

This image shows the SH3 average dashboard performance improvement, broken down by runtime. The average tends to move more on longer-running searches, although there is less data to compare. Improvements here are mostly sub-5%, excluding the 600+ second category, which saw a 40% improvement:

This image shows the SH3 average dashboard performance improvement, broken down by search type:

This image shows the SH3 perc95 dashboard performance improvement, broken down by runtime:
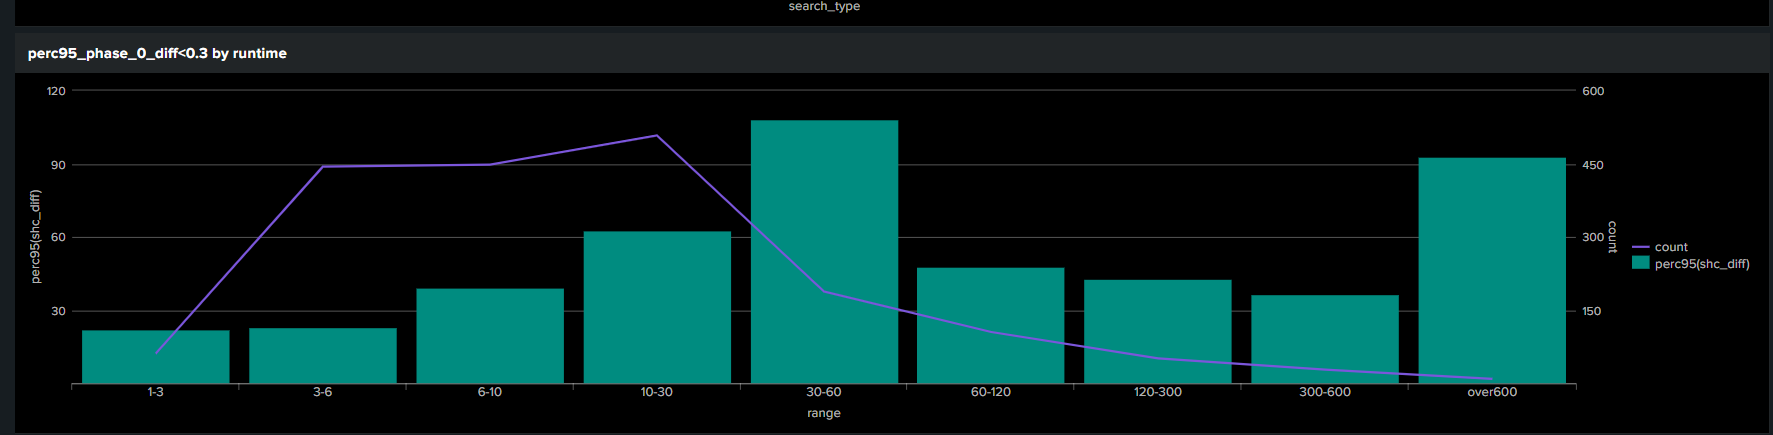
This image shows the SH3 perc95 dashboard performance improvement, broken down by search type:

SH3 saved searches
This image shows the SH3 saved search variance between search runs. The variance is again quite low here. It's consistent between runs, and there are more statistics available than for the dashboard numbers:

This image shows the SH3 average saved search performance improvement, broken down by runtime. The performance improvement in this cluster is again sub-5%, excluding 600+ second searches, which achieve a 16% performance improvement:

This image shows the SH3 average saved search performance improvement, broken down by search type:
This image shows the SH3 perc95 saved search performance improvement, broken down by runtime:

This image shows the SH3 perc95 saved search performance improvement, broken down by search type. Some searches see a significant benefit, with the largest again in the 600+ second category. This category also has the least statistics available, so the figures here might be less reliable:

Conclusion
The performance improvement measured here is significant across real-world search head and indexer clusters. Compared with the previous hardware change, which achieved around a 5% increase in saved search performance for SH1, this version upgrade achieved a greater improvement in the statistics, even after excluding outliers. This suggests that changes made between versions can result in meaningful performance improvements over time, even when they are not called out in release notes.
As with any release, check the Splunk Enterprise release notes for known issues before upgrading, and where possible move to the latest maintenance release within your target major/minor version.
Search details and result counts
Determining the performance per search
The search used for this comparison builds on the one shown in Comparing search head performance gains after upgrading a low-utilization cluster, with some minor tweaks that could be tuned further:
| multisearch
    [ search index=_introspection sourcetype=search_telemetry `allsearchheads` perf.search_runtime_secs>2 search_id!=1*
    | rename desc.app AS app
    | fields phases.phase_0.elapsed_time_aggregations.max, phases.phase_1.elapsed_time_aggregations.max, host, search_id app ]
    [ search index=_audit `allsearchheads` info=completed total_run_time>2 search_id="'scheduler*" has_error_warn=false fully_completed_search=true
    | eval search_id=trim(search_id,"\'")
    ``` this is the basic version, but it didn't match 100% of searches in my environment that like to include " symbols, the alternative is very specific and may break if the format of audit.log changes
    | rex ", savedsearch_name=\"(?P<savedsearch_name>[^\"]+)\","
    ```
    | rex ", savedsearch_name=\"(?P<savedsearch_name>.*?)\",( search_type=[^,]+,)? search_startup_time"
    | rex "(?s), search='(?P<search>.*)\]$"
    | rex field=search mode=sed "s/\n/ /g"
    | rex field=search mode=sed "s/```.*?```/ /g"
    | eval search=if(substr(search,len(search),len(search)-1)=="'",substr(search,0,len(search)-1),search)
    ``` subsitute macros/datamodels/tags/eventtypes to get a slightly clearer idea of command in use, optional (borrowed from Alerts for Splunk Admins search "SearchHeadLevel - Search Queries summary exact match". Removed from this example ```
    | rex field=search "^(\s*\|\s*)?\s*(?P<command>\S+)"
    | rex field=search "(\||^)\s*(?P<subsearch>(append|union|multisearch|set|appendcols|appendpipe|join|map))"
    | eval subsearch=if(isnotnull(subsearch),"true","false")
    ``` this determines the type of the first command, you could for example, do a inputlookup and then a | append search. But, the append becomes a sub-search which is not measured in the sourcetype=search_telemetry, the phase 1 will also be total search time...```
    | eval search_type=case(command="ldapsearch" OR command="dbxquery","remote_server",command="tstats" OR command="metadata" OR command="eventcount","metadata",command="makeresults" OR command="inputlookup" OR command="rest" OR command="loadjob" OR command="noop" OR command="stats","local",match(command,"^trackme"),"customcommand",command="multisearch" OR command="MULTISEARCH" OR command="union" OR command="UNION" OR command="savedsearch" OR command="datamodel" OR command="from" OR command="set","search",command="`","search",1=1,command)
    | eval search_source="savedsearch"
    | fields total_run_time, savedsearch_name, search_id, result_count, event_count, scan_count, search_type, app subsearch search_source host ]
    [ search index=_audit `allsearchheads` info=completed total_run_time>2 has_error_warn=false fully_completed_search=true provenance="UI:Dashboard:*"
    | eval search_id=trim(search_id,"\'")
    | eval time_period=api_lt-api_et
    | eval time_period=round(api_lt-api_et)
    ``` round the time for dashboards that use a snap-to time, this ensures we don't breakdown every dashboard search that is pinned to a particular hour into a unique field for comparison. Tips welcome ```
    | eval time_period = case(
        time_period >= 1296000, ceil(time_period/86400)*86400,
        time_period >= 14400 , ceil(time_period/60/60)*3600,
        time_period >= 300, ceil(time_period/60)*60,
        true(), time_period
        )
    | eval time_period=if(api_et=="N/A","alltime",time_period)
    ``` this is the basic version, but it didn't match 100% of searches in my environment that like to include " symbols, the alternative is very specific and may break if the format of audit.log changes
    | rex ", savedsearch_name=\"(?P<savedsearch_name>[^\"]+)\","
    ```
    | rex ", savedsearch_name=\"(?P<savedsearch_name>.*?)\",( search_type=[^,]+,)? search_startup_time"
    | eval savedsearch_name=provenance . "_" . savedsearch_name . "_" . time_period
    | rex "(?s), search='(?P<search>.*)\]$"
    | rex field=search mode=sed "s/\n/ /g"
    | rex field=search mode=sed "s/```.*?```/ /g"
    ```| regex search!="(earliest|latest)\s*=\s*"```
    | eval search=if(substr(search,len(search),len(search)-1)=="'",substr(search,0,len(search)-1),search)
    ``` subsitute macros/datamodels/tags/eventtypes to get a slightly clearer idea of command in use, optional (borrowed from Alerts for Splunk Admins search "SearchHeadLevel - Search Queries summary exact match". Removed from this example ```
    | rex field=search "^(\s*\|\s*)?\s*(?P<command>\S+)"
    | rex field=search "(\||^)\s*(?P<subsearch>(append|union|multisearch|set|appendcols|appendpipe|join|map))"
    | eval subsearch=if(isnotnull(subsearch),"true","false")
    ``` this determines the type of the first command, you could for example, do a inputlookup and then a | append search. But, the append becomes a sub-search which is not measured in the sourcetype=search_telemetry, the phase 1 will also be total search time...```
    | eval search_type=case(command="ldapsearch" OR command="dbxquery","remote_server",command="tstats" OR command="metadata" OR command="eventcount","metadata",command="makeresults" OR command="inputlookup" OR command="rest" OR command="loadjob" OR command="noop" OR command="stats","local",match(command,"^trackme"),"customcommand",command="multisearch" OR command="MULTISEARCH" OR command="union" OR command="UNION" OR command="savedsearch" OR command="datamodel" OR command="from" OR command="set","search",command="`","search",1=1,command)
    | eval search_source="dashboard"
    | fields total_run_time, savedsearch_name, search_id, result_count, event_count, scan_count, search_type, app, subsearch, search_source, host ]
| eval search_head=host
| eval search_head_cluster=`search_head_cluster`
| selfjoin search_id app search_head_cluster
| table _time, phases.phase_0.elapsed_time_aggregations.max, phases.phase_1.elapsed_time_aggregations.max, host, savedsearch_name, total_run_time, result_count, event_count, scan_count search_type app subsearch search_source search_head_cluster
``` TODO test 24h vs 1 hour ```
| bin _time span=24h
```| bin _time span=1h ```
| eval type=if(_time<1786228200,"9.3.3","10.2.5")
| stats count, avg(phases.phase_1.elapsed_time_aggregations.max) AS avg_sh_time, avg(phases.phase_0.elapsed_time_aggregations.max) AS avg_indexer_time, avg(total_run_time) AS total_run_time, avg(scan_count) AS scan_count, avg(event_count) AS event_count, avg(result_count) AS result_count, values(subsearch) AS subsearch, stdev(phases.phase_1.elapsed_time_aggregations.max) AS phase_1_stdev, stdev(phases.phase_0.elapsed_time_aggregations.max) AS phase_0_stdev by savedsearch_name, _time, search_type, app, search_source, search_head_cluster, type
| eval phase_1_diff=round(phase_1_stdev/avg_sh_time,3), phase_0_diff=round(phase_0_stdev/avg_indexer_time,3)
| eventstats perc95(phase_1_diff) AS phase_1_diff, perc95(phase_0_perc) AS phase_0_diff, avg(phase_0_diff) AS avg_phase_0_diff, avg(phase_1_diff) AS avg_phase_1_diff by savedsearch_name, search_type, app, search_source, search_head_cluster
| eval day=strftime(_time, "%a")
| eval hour=strftime(_time, "%H")
| sort 0 savedsearch_name type
    ``` there may be an easier way to do this, but this works ```
| streamstats window=1 global=f current=f reset_on_change=true values(avg_sh_time) AS avg_new_sh_time, values(avg_indexer_time) AS avg_new_indexer_time, values(scan_count) AS prev_scan_count, values(event_count) AS prev_event_count, values(result_count) AS prev_result_count by savedsearch_name, search_head_cluster
| eval shc_diff=((avg_sh_time/avg_new_sh_time)-1)*100, indexer_diff=((avg_indexer_time/avg_new_indexer_time)-1)*100
| eval ratio=(100/avg_sh_time)*avg_indexer_time
| foreach avg* phase_* ratio shc_diff total_run_time [eval <<FIELD>>=round('<<FIELD>>',2)]
| rangemap field=avg_sh_time 1-3=1-3 3-6=3-6 6-10=6-10 10-30=10-30 30-60=30-60 60-120=60-120 120-300=120-300 300-600=300-600 default=over600
``` TODO, breakdown via _time, perhaps 1 hour blocks of the day or similar, only include savedsearches not modified after a chosen date into the data?
Eliminate searches that vary too much randomly so they are excluded.
Perform maths on how many searches run with random time periods and what time blocks do they fall into...use that to calculate a more accurate % numberI considered exclusion:
To avoid including data from dashboards that had changed, the following search was used to identify recently updated dashboards, which could then be repeated for saved searches:
| rest /servicesNS/-/-/data/ui/views f=title f=updated f=eai:acl* splunk_server=local timeout=900
| eval updated=strptime(updated,"%Y-%m-%dT%H:%M:%S%z")
| where updated>1784988000
| rename eai:acl.app AS app
| eval search_source="dashboard"
| eval savedsearch_name="UI:Dashboard:" . title . "*"
| table app, savedsearch_name, search_source
The number of changes identified this way was minimal compared to the overall volume used in the comparison, so this extra information was not included per search head cluster in the final results. The statistics from the original search were used instead.
Result counts per graph
Result-count data provides context around the percentage increase on each graph, since some ranges do not have as many results as others. For the full breakdown of result counts by search head cluster, search source, and search type, see the original article this comparison is based on.
Next steps
You might find the following resources useful for implementing the guidance in this article:
- Splunk Lantern Article: Comparing search head performance gains after upgrading a low-utilization cluster
- Splunk Lantern Article: Comparing search head hardware changes and their impact on Splunk platform search performance