

Detecting security anomalies with the Cisco Deep Time Series Model
If you've been following Splunk AI Toolkit (formerly MLTK) releases, you might have noticed a new capability in version 5.7.3 that matured further in version 6.0.0: the Cisco Deep Time Series Model (CDTSM). CDTSM is a pretrained generative AI model built for machine data. There's no fit step, no training search, and no model to maintain. You point it at a time series and it calculates what normal looks like.
This article focuses on how to put CDTSM to work for security detections. For a deeper look at the model itself, see the official feature documentation.
Why not just use | stats stdev or DensityFunction?
Detection engineers have been using both for years, and they work. So why change?
| stats stdev is fast and simple, but it assumes your data is normally distributed and has no concept of time. A spike in failed logins at 2am looks the same to stdev as one at 9am on a Monday. Context is everything in security, and stdev has none.
DensityFunction in the AI Toolkit is more sophisticated. It models the distribution of a metric and can flag outliers against that learned distribution. But it has a few friction points that make it harder to operationalize at scale:
- You need a separate fit search to train the model and a scheduled search to keep it current.
- The model is stored as a named artifact that needs managing.
- It doesn't natively handle seasonality, meaning a metric with weekly or daily cycles produces noisy results unless you pre-process the data.
- Tuning it for a specific security use case often requires iterative experimentation that's hard to do quickly.
CDTSM removes most of that friction. There's no fit step. It handles overlapping seasonality (hourly, daily, weekly) automatically, because those patterns are baked into the model from pretraining. You write one SPL command, add it to a search, and you have anomaly detection.
The trade-off is that CDTSM requires a minimum of 60 data points at a fixed time resolution. If your data is sparse or irregular, DensityFunction might still be the better tool. For security teams specifically, CDTSM is a strong fit for any KPI you're already trending over time.
Security use cases worth exploring
Before getting into the SPL, here are some signals that CDTSM suits well in a security context:
- Authentication anomalies: Unusual spikes or drops in failed login attempts per user or source IP.
- Data exfiltration signals: Abnormal outbound data volumes by user, host, or destination.
- Lateral movement indicators: Unexpected increases in internal connection counts per host.
- Process execution anomalies: Deviations in process launch frequency per endpoint.
- DNS anomalies: Unusual query rates that could indicate beaconing or tunneling activity.
The worked example below is a single, environment-wide series (PDNS blocks), but the approach applies directly to any of the above where you have one clear signal to trend.
Prerequisites
- Splunk AI Toolkit version 6.0.0, installed from Splunkbase.
Key tuning parameters
The following parameters are used in the worked example. They're summarized here for reference before you begin.
| Parameter | Description |
|---|---|
mode |
Set to anomaly. The alternative, forecast, predicts future values without flagging anything. |
method |
quantile for a single series; iqr_residual for grouped or fleet detection. |
conf_interval |
Width of the base confidence band, from the model's own forecast quantiles. Supported values: 20, 40, 50, 60, 80, 90, 98. |
multiplier |
Your main sensitivity dial. How far outside the confidence band a point must sit before it's flagged. |
on_span / off_span |
How many consecutive points must breach the band before a segment starts or ends. Set both to 1 to flag on any single anomalous point. |
detection_window_earliest / detection_window_latest |
The window CDTSM evaluates for anomalies (capped at 24 hours wide). See the worked example below for important caveats. |
For the full parameter reference including forecasting-specific options, see the CDTSM documentation.
How to use Splunk software for this use case
The core SPL pattern is:
<your timechart search> | apply CDTSM <field> mode=anomaly
Everything else is optional tuning using the parameters described above.
Detecting anomalies in a single time series
This example detects anomalies in the overall volume of PDNS blocks across your environment.
index=dns_blocks
| timechart span=1h count
| apply CDTSM count mode=anomaly method=quantile conf_interval=60 multiplier=10 on_span=1 off_span=1 detection_window_latest=-1h
Because this is a single environment-wide series with a consistent daily and weekly pattern, method=quantile is the right choice. The model compares each observed value directly against the forecast band, and the seasonality handling means the band naturally widens during high-activity periods and tightens during quiet ones, reducing noise without any manual configuration.
A few parameter choices worth explaining:
conf_interval=60sets the base confidence band using the model's own forecast quantiles (p20–p80). This is the anomaly mode default, and it's already doing seasonality-aware work for you: the band's width shifts as the model's uncertainty changes throughout the day and week. You shouldn't need to change this for most security use cases.multiplier=10is your sensitivity dial. Whereconf_intervalsets the shape of "normal",multipliersets how many multiples of that band a point must clear before it's flagged. This is the one parameter to adjust when tuning: lower it to catch more, raise it to reduce noise.on_span=1 off_span=1tells CDTSM to flag on any single anomalous point, rather than waiting for a run of consecutive breaches. For an hourly security search where you want to know about a single unusual hour immediately, this is the right default. The default behavior requires 2 of 3 consecutive points outside the band before starting a segment, which is better suited to smoothing noisy operational metrics than to catching a single spike.detection_window_latest=-1hexcludes the current, still-filling hourly bucket from evaluation. Without this, a search that runs partway through the hour evaluates a bucket with only partial data, which structurally looks low and can get flagged as a false anomaly.
Running this search gives you a statistics table by default. To see an Anomaly Detection Chart, switch to the Visualization tab and select that chart type. It plots the observed series against the forecast band and shades any anomaly regions, which makes it much faster to judge the effect of a tuning change than reading anomaly_state values in a table.
The screenshots below show the effect of changing multiplier. The search and conf_interval=60 are the same in both; only the multiplier value changes.
With multiplier=20, no anomaly is flagged. The red threshold band is wide enough that even the sharp rise in blocked queries stays within tolerance.

With multiplier=10, an anomaly region appears (shown as a red rectangle). The tighter threshold band means the same rise in blocked queries now crosses it.
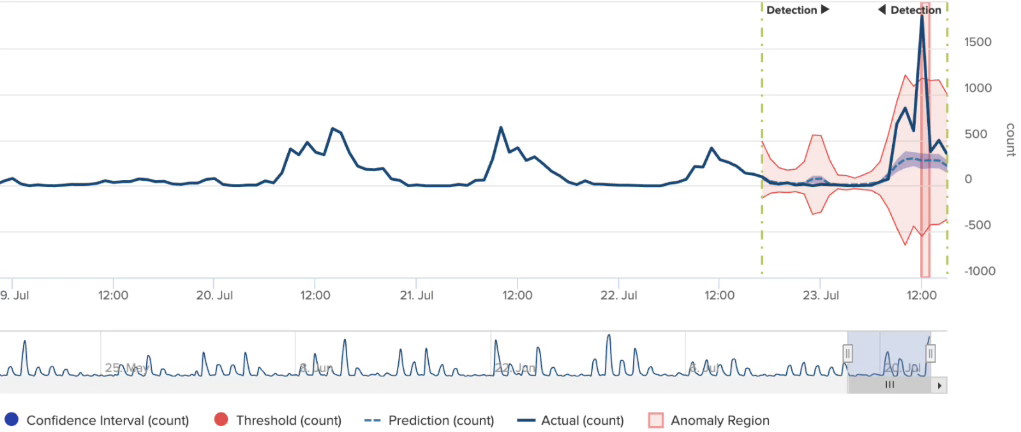
This is the core tuning loop for this use case: leave conf_interval alone, and adjust multiplier until the detection rate matches what your environment needs.
Changing the window width changes the forecast itself, not just what gets evaluated. Everything before detection_window_earliest is treated as known history; everything after is forecast and checked for anomalies. Because CDTSM forecasts autoregressively, shifting that boundary changes how much history the model conditions on, which shifts the forecast for every point in the window, even ones whose data hasn't changed. In testing, moving the boundary by a single hour flipped previously normal points to anomalous. Tune with the same window width you'll run in production; a wide tuning window is directional only.
Turning the anomaly detection search into a correlation search
After you're happy with the tuning, the anomaly detection search becomes a correlation search like any other. The field that matters is anomaly_state, exposed after renaming CDTSM's count.* output fields:
index=dns_blocks earliest=-90d@d
| timechart span=1h count
| apply CDTSM count mode=anomaly method=quantile conf_interval=60 multiplier=10 on_span=1 off_span=1 detection_window_earliest=-4h detection_window_latest=-1h
| rename count.* AS *
| where anomaly_state="ANOMALOUS"
A few things worth being deliberate about when scheduling this:
earliest=-90d@dgives the model enough history to forecast from. It isn't the detection window, just backfilling context, and can be set as a detection parameter rather than in the SPL.- For high-volume data sources, running 90 days of raw search on every scheduled execution might not be practical. Consider pre-summarizing into a daily or hourly summary index or into an accelerated data model, and then pointing CDTSM at that instead of raw events.
- Keep the detection window the same width you tuned with. Per the caution above, a narrowed production window won't behave like the one you tuned at.
- Schedule hourly, offset a few minutes past the hour (for example, X:11), to give indexing lag some room and to avoid evaluating a partially-filled hour.
- Throttle by
_time, with a 1-day window. Because the detection window spans several hours, the same anomalous bucket can appear in results across more than one consecutive run before it ages out. Throttling on_timestops a single anomaly from firing repeat alerts as it gets re-evaluated.
Next steps
CDTSM makes threshold-free, AI-driven anomaly detection accessible for security teams who know the Splunk platform but don't have a data science background. The fit/apply complexity that made DensityFunction-based detection feel like specialist work is gone. You get seasonality-aware, probabilistic anomaly detection with a single SPL command.
The pattern above, a single environment-wide series taken from raw SPL through to a tuned, alert-ready correlation search, covers a good chunk of the security use cases you'll want to start with.
Finally, you might find the following resources useful for implementing the guidance in this article:
- Splunk Help: Algorithms in the AI Toolkit